Inferred
Commercial model
Open source profile signal; exact enterprise terms need buyer review.
View source
LLM APIs
Open-source router for Claude Code that lets builders route coding-agent requests across OpenAI-compatible model providers and custom backends.
Generated from similarity, co-save, category, project, and adoption signals.
Comparisons, category adoption data, and shortlist guides that answer the questions this profile raises next.
Source-labeled signals for cost, reliability, security, integration, and adoption proof. Missing compliance evidence is shown as a gap, not guessed.
Open source profile signal; exact enterprise terms need buyer review.
View sourceNo status page, uptime, or SLA evidence attached
Shortlist only after verifying Reliability and Security/compliance.
These are source-linked enrichment paths for missing fields. They are treated as proxies until claimed-company data and first-party tokens& adoption events replace them.
Hackathons, workshops, office hours, launches, and partner challenges tied to this product.
No public events yet
Claimed teams can add hackathons, webinars, office hours, and challenges, then measure attendee to usage ROI.
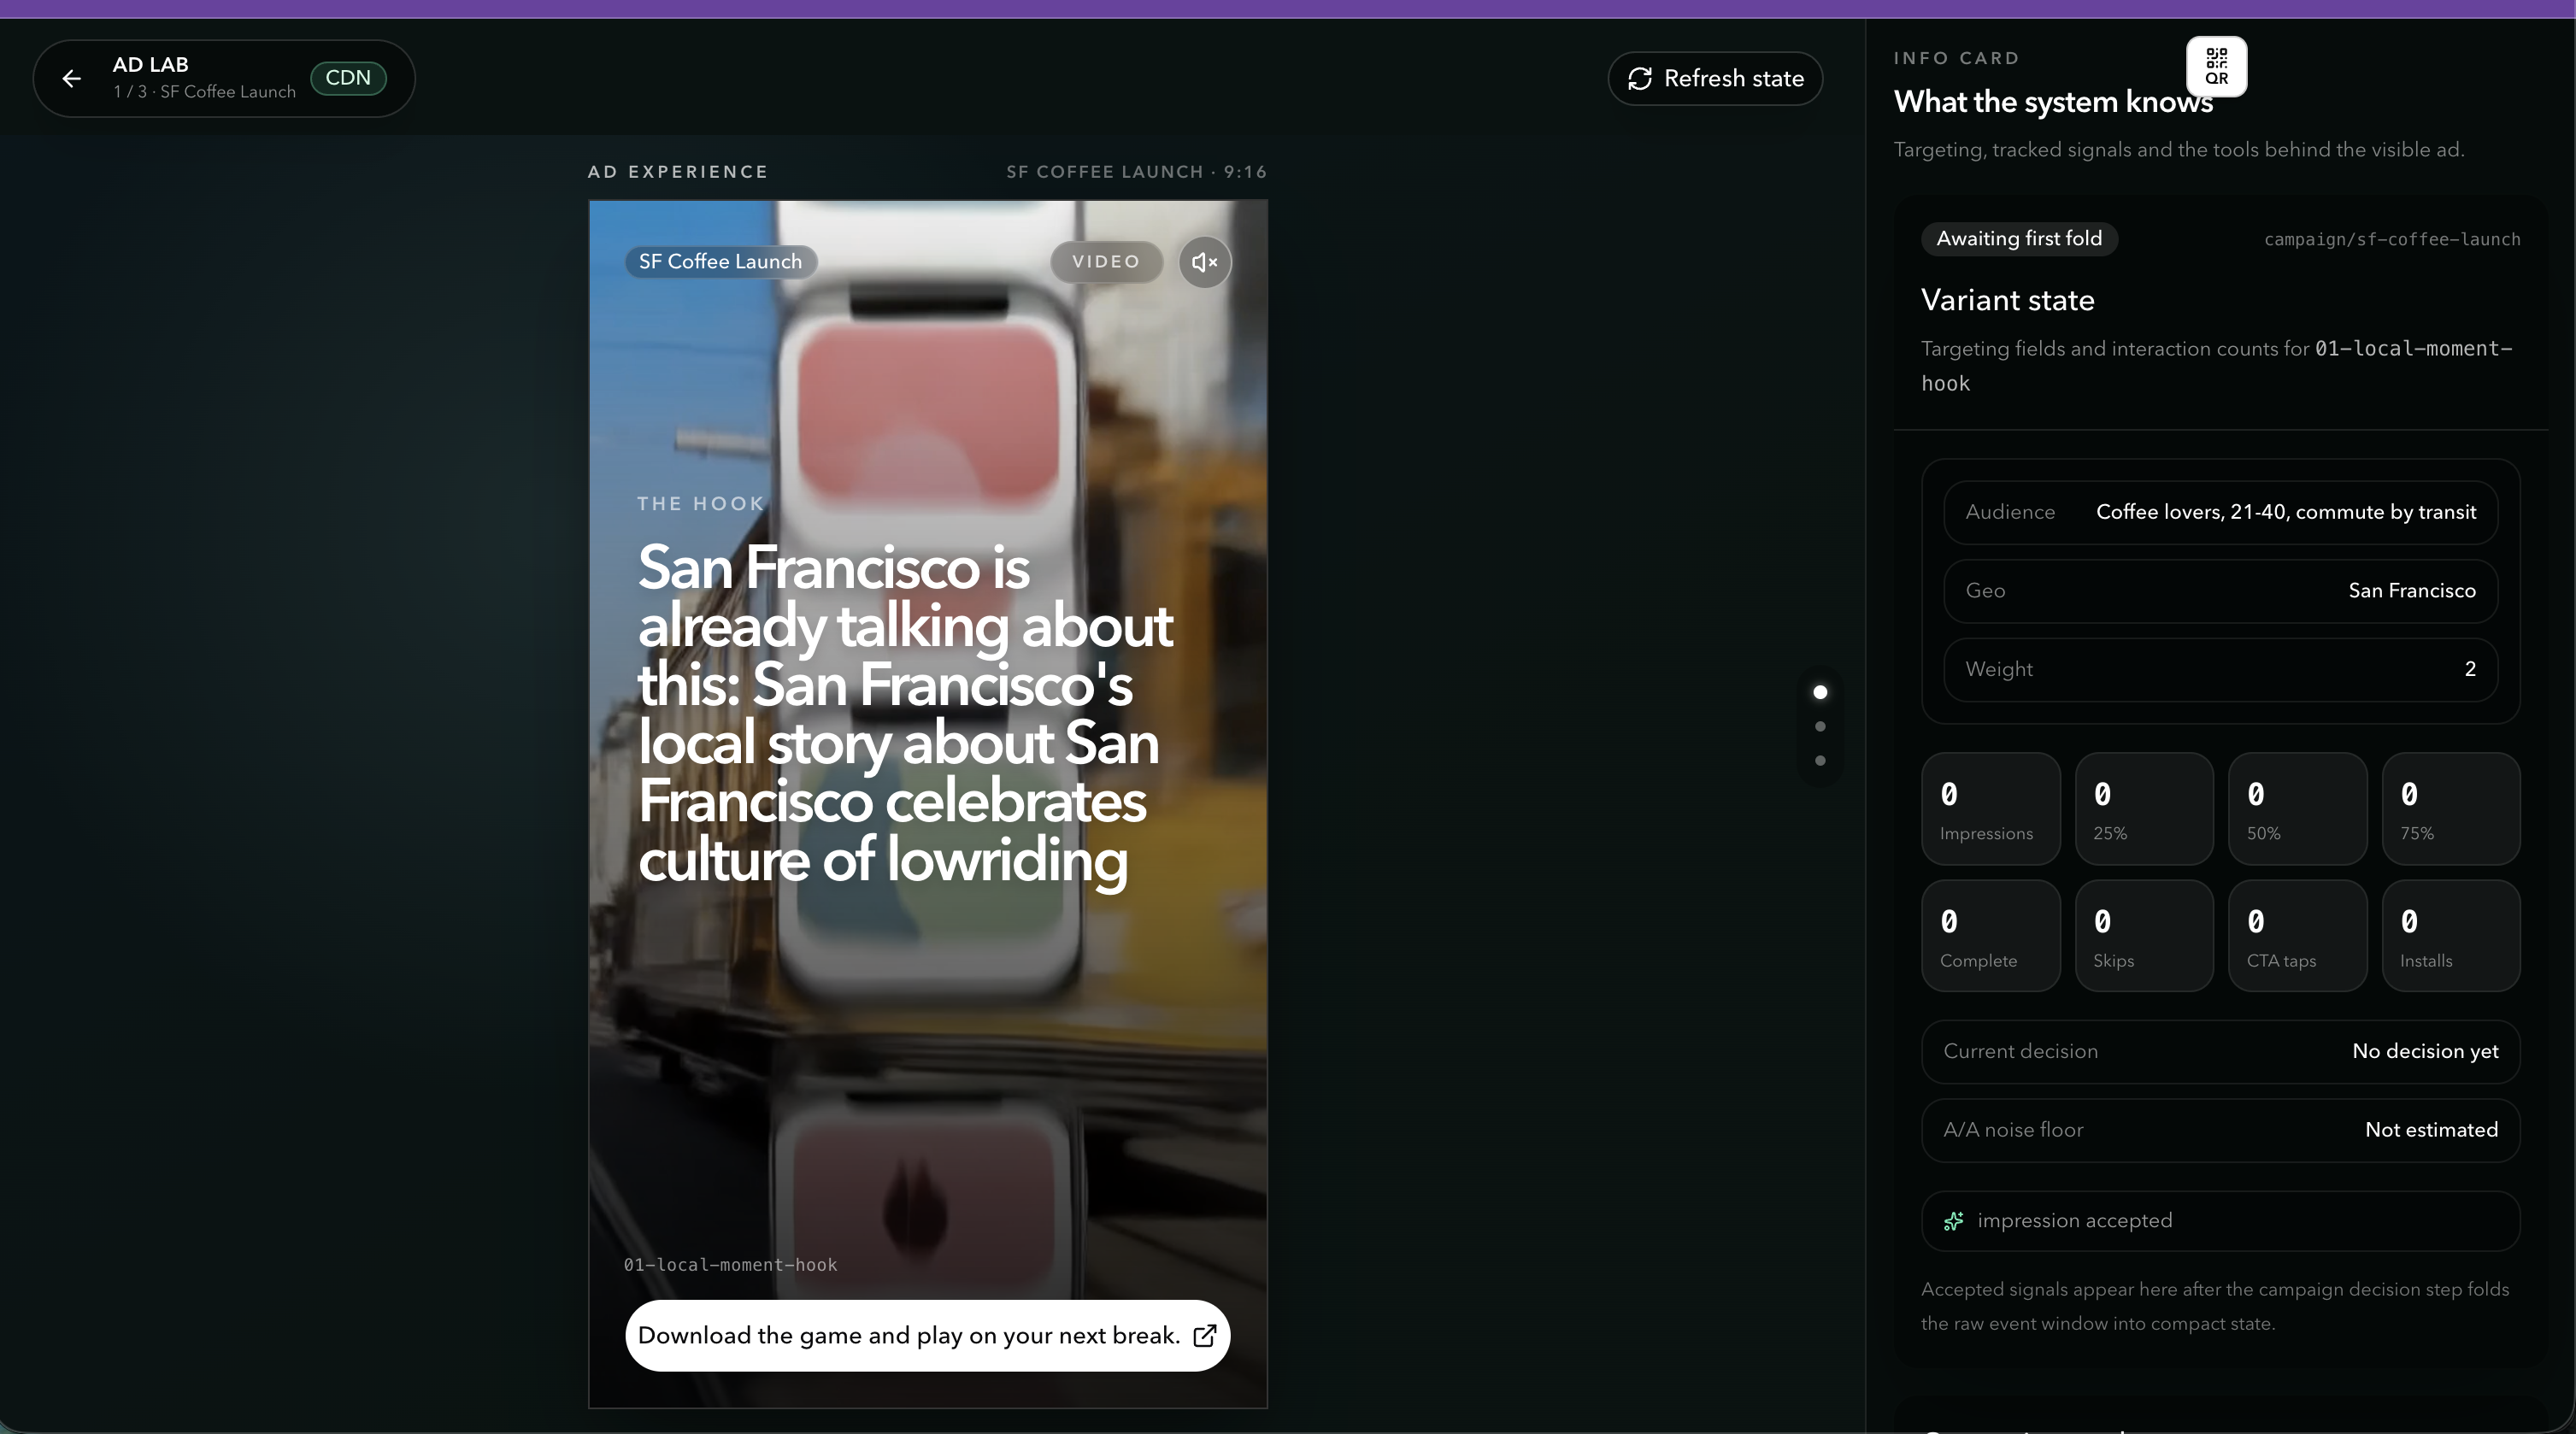
We made a platform for generating hyper-personalized, topical local ads It is aimed at helping local businesses create advertisements that tie their products to recent local events and topics. Local small businesses tell us their city and what they want to promote. Our platform uses Nimble to find recent news stories in the area, then leverages Black Forest Labs FLUX video models to create a set of 10-second campaign creatives. Each ad references a different local news story, allowing us to identify which topics resonate best with each audience. We leverage Tinybird to log all inputs (instructions from advertisers), intermediate outputs (news stories and Black Forest prompts), and final outputs (the generated videos), as well as internal logs for generation failures. Our code then screens for bugs and failures and suggests fixes before executing any new calls, so compute and tokens are not wasted before issues are resolved. These logs will also allow us to identify the ad characteristics that perform best, so future ad generation can learn from previous campaign performance.
Developer identities, account mapping, retention cohorts, and competitor overlap are available on Growth and Enterprise plans.
Same category
Own Claude Code Router? Generate its adoption badge embed, or claim the profile to send verified usage events.
No security, trust, or compliance source attached
API available with docs/profile signal
View source2 verified adoption signals
Vendors receive anonymous aggregate evaluation demand by default. Account details are shared only after explicit buyer contact or consent.
Request vendor contact OpenAIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.
 NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.CodexpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.
 TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.
 Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.
 cursorpendingAdded by the builder while publishing bucketlist #6. Pending catalog review before becoming a public tool profile.
 VS CodependingAdded by the builder while publishing Local Ad Platform (LH). Pending catalog review before becoming a public tool profile.
What happens when an AI agent remembers the task but forgets what it was allowed to do? Mission Continuity is a working experiment built with Claude, Pydantic AI, and Sentience Governor. Our agent investigates a synthetic billing dispute but cannot issue refunds, modify records, delete information, or contact the customer. We compare two architectures across context compaction. The baseline carries forward an AI-generated summary. The governed version also preserves critical evidence verbatim and reintroduces the original Mission Kernel on every request. Sentience Governor records execution and flags scope violations; the application manages compaction and guards prohibited actions. In one recorded baseline run, the agent attempted to contact the customer after restrictions disappeared from its summary. Governor flagged the attempt; no real customer was contacted. The governed run retained all six tracked facts and mission limits without a prohibited attempt. In a controlled omission test, baseline retained 2/6 facts versus governed 6/6. We also tested Liquid AI summarization offline and exported 1,241 execution-evidence rows to RawTree for SQL analysis. A fresh live governed run completed 27 tool calls and one compaction, retained 6/6 facts, and produced a report scoring 4/5 against a withheld answer key. The project includes a working Streamlit console, verifiable replays, and reproducible experiments.
Listed tools (6)
Scroll for more Liquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.
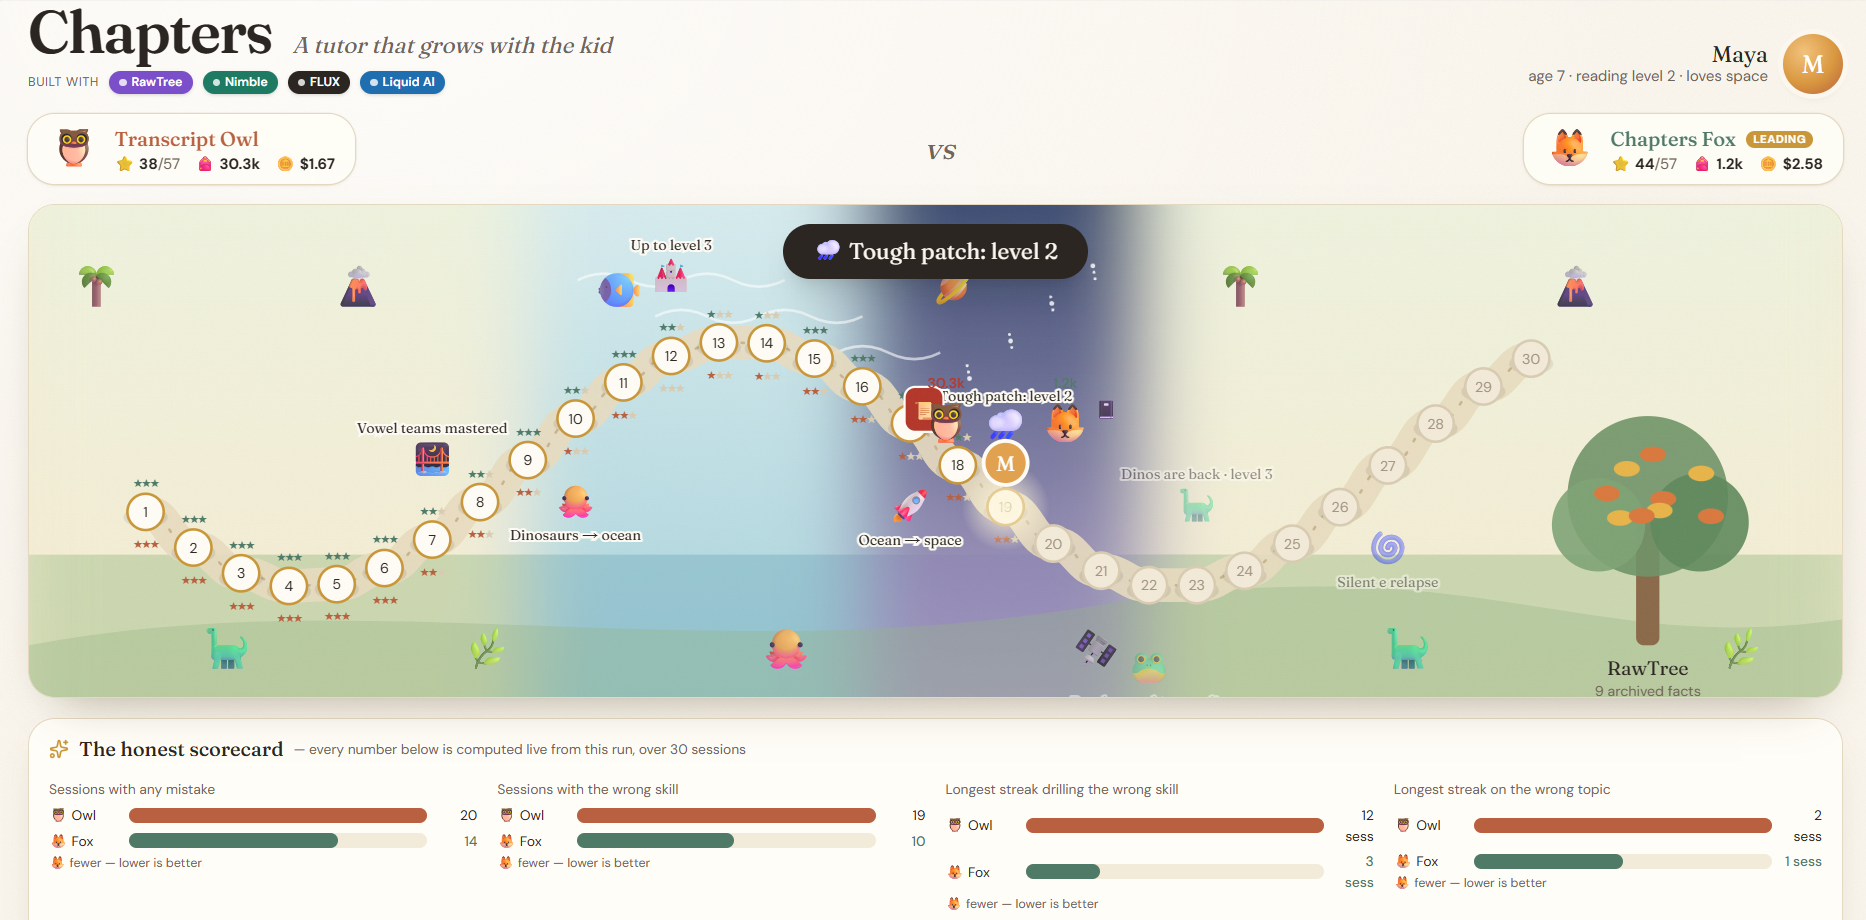
Chapters is a reading tutor that runs a full 30-session semester with one kid, writing her a new book each time based on what it currently believes about her level, interests, and skill gaps instead of dragging the whole session history into every prompt, it keeps a small editable model of the student and updates that directly. Viewers can see the comparison between Fox( the better tutor ) and the Owl( the baseline tutor with no understanding from memory ) and see how ours is a strongly better agent. How it works: each session the tutor reads its current model of the kid, generates a book for her, she reads and reacts, and the tutor revises the model adding, updating, or archiving specific facts rather than appending a transcript. A separate small model checks in every couple session to catch facts that have gone stale or contradict new evidence. Where the tools come in: - RawTree is the permanent archive: everything the model lets go of still lands here, queryable with plain-English-to-SQL. - Liquid AI's LFM2 is that periodic memory review, running locally. - Nimble pulls a real, current web fact into each story. - Black Forest Labs FLUX paints a real cover for every book. Result: a tutor whose prompt stays flat (~1,100 tokens) for the whole semester and ends up more accurate than one that just keeps appending everything (which balloons to ~49,000 tokens).
Listed tools (6)
Scroll for moreLiquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.CodexpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Team proof is pending until the product profile is claimed.
| Pending review |
| Insufficient cohort50% confidence |
Category rank AgentRank methodology · Pending | Pending review | Rank pending40% confidence |
Team proof Domain, social, and team evidence · Live | Pending review | Team signal exists45% confidence |
Security and enterprise readiness Docs, compliance, protocol, and readiness signals · Pending | Pending review | Security proof pending38% confidence |
0
Known active developer activity
Unclaimed
Owner action needed
Agent-readable protocol evidence raises trust and commercial readiness.
Benchmark proof pending
Attach latency, cost, accuracy, reliability, or eval evidence to unlock the performance component.
Enterprise verification can enrich evidence and export proof packages, but cannot buy rank.
Claim this tool to see who is evaluating itClaim Claude Code Router before competitors use this profile as proof.
Connect usage events, resolve developer identities, and see which accounts are evaluating Claude Code Router.
Claim this tool to see who is evaluating it