
Explore public projects, their source code, demos, and tools. Sign in to draft your own project, then choose when to publish it.
Curated project ideas to help you choose a stack. Sign in to create a plan; publish your project when you have work to share.
Turn a fresh repo, demo, Show HN, or hackathon launch into a public proof page with stack notes, launch context, and real build evidence.
Suggested tools
I used Nimble, Raw Tree and BFL. Nimble was pointed at a location in SF to pull in all of the local events for a neighborhood. That data was placed into raw tree to house an event calendar and for video creation. BFL was handed a generic written news script along with the event data and was told to create a news videos of the upcoming events.
Listed tools (3)
 NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.
 TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.
 Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.

An always-on newsroom agent whose memory, analytics and flight recorder all live in one schemaless database. Watch. Every hour the full GH Archive firehose lands in RawTree via server-side URL ingest, raw JSON with no schema. A week of it is 14.4M events (2.15 GB).Detect. RawTree SQL ranks candidates across the firehose, then each candidate's own event feed is logged to measure exact star velocity. A breakout opens a story.Remember. Before anything else, the desk asks RawTree what it already reported about this repo, so follow-ups say what changed instead of repeating themselves.Triage. A Liquid LFM2.5 model on the laptop labels the repo before any paid call.Research. A Nimble Web Search Agent finds out why it is trending and returns cited, confidence-graded claims.Broadcast. An OpenAI-compatible LLM writes a 12-second script, FLUX 3 renders the anchor reading it, and the control room airs it with the sources as on-screen captions.Every step is written to RawTree as an event. The same log drives the live control room, lets a restarted worker pick up unfinished stories, and is what judges can query through Ask the desk, an agent that combines Nimble's web tools with RawTree SQL.
Listed tools (4)
Scroll for moreTinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile. Liquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.
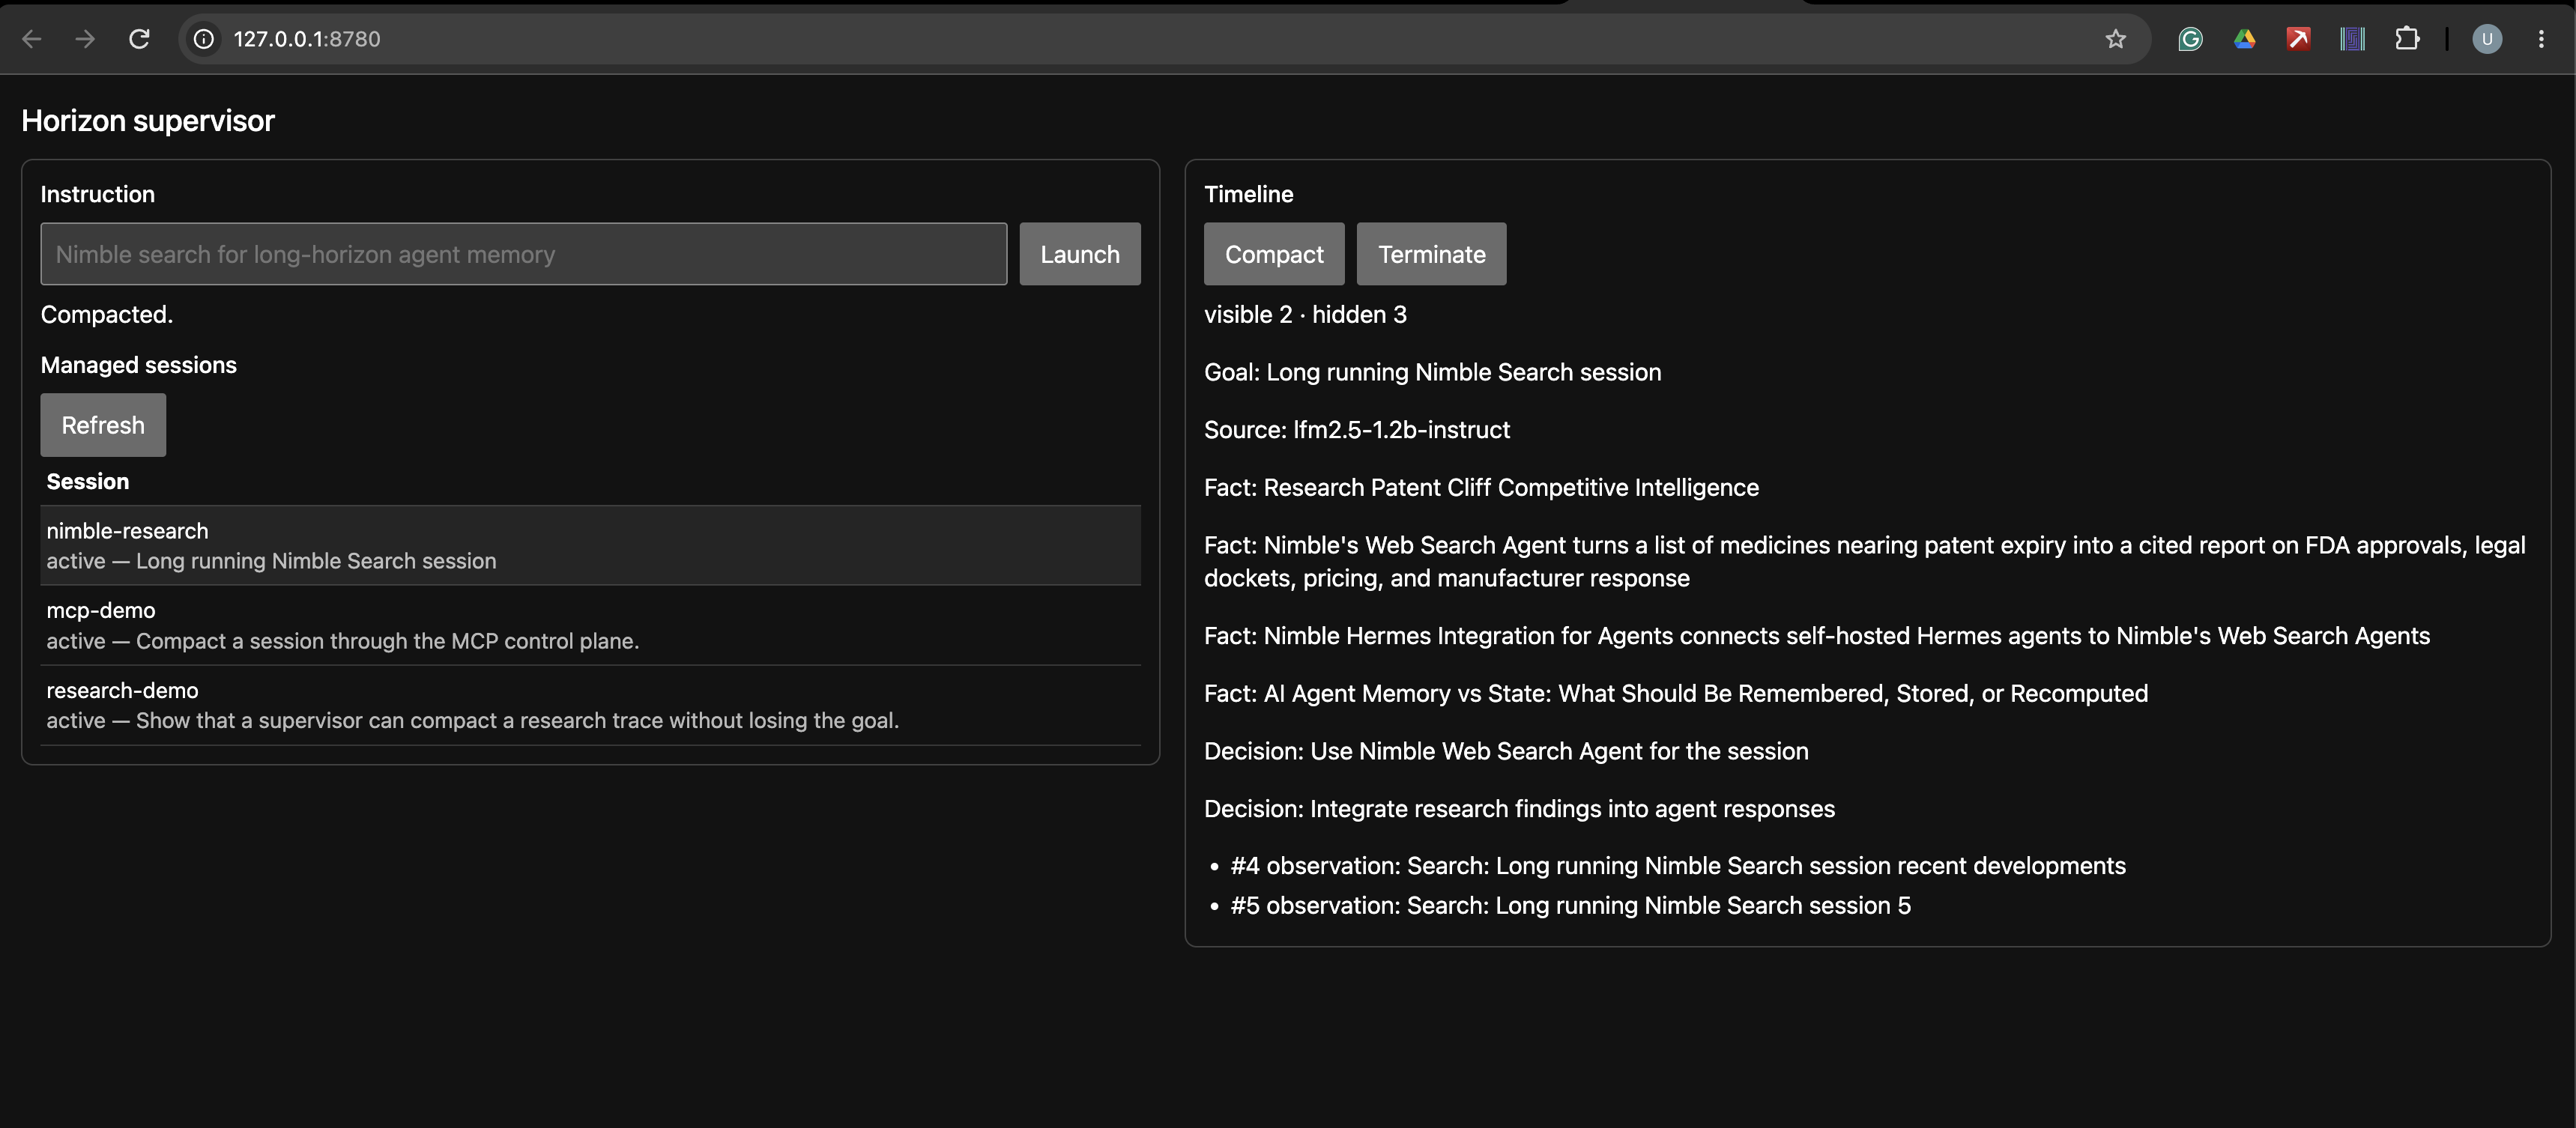
Horizon manages long-running agent sessions (e.g. Nimble search session). It provides a list of managed sessions, shows the timeline, folds older events into a working state, and can terminate the session.
Listed tools (3)
NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Liquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.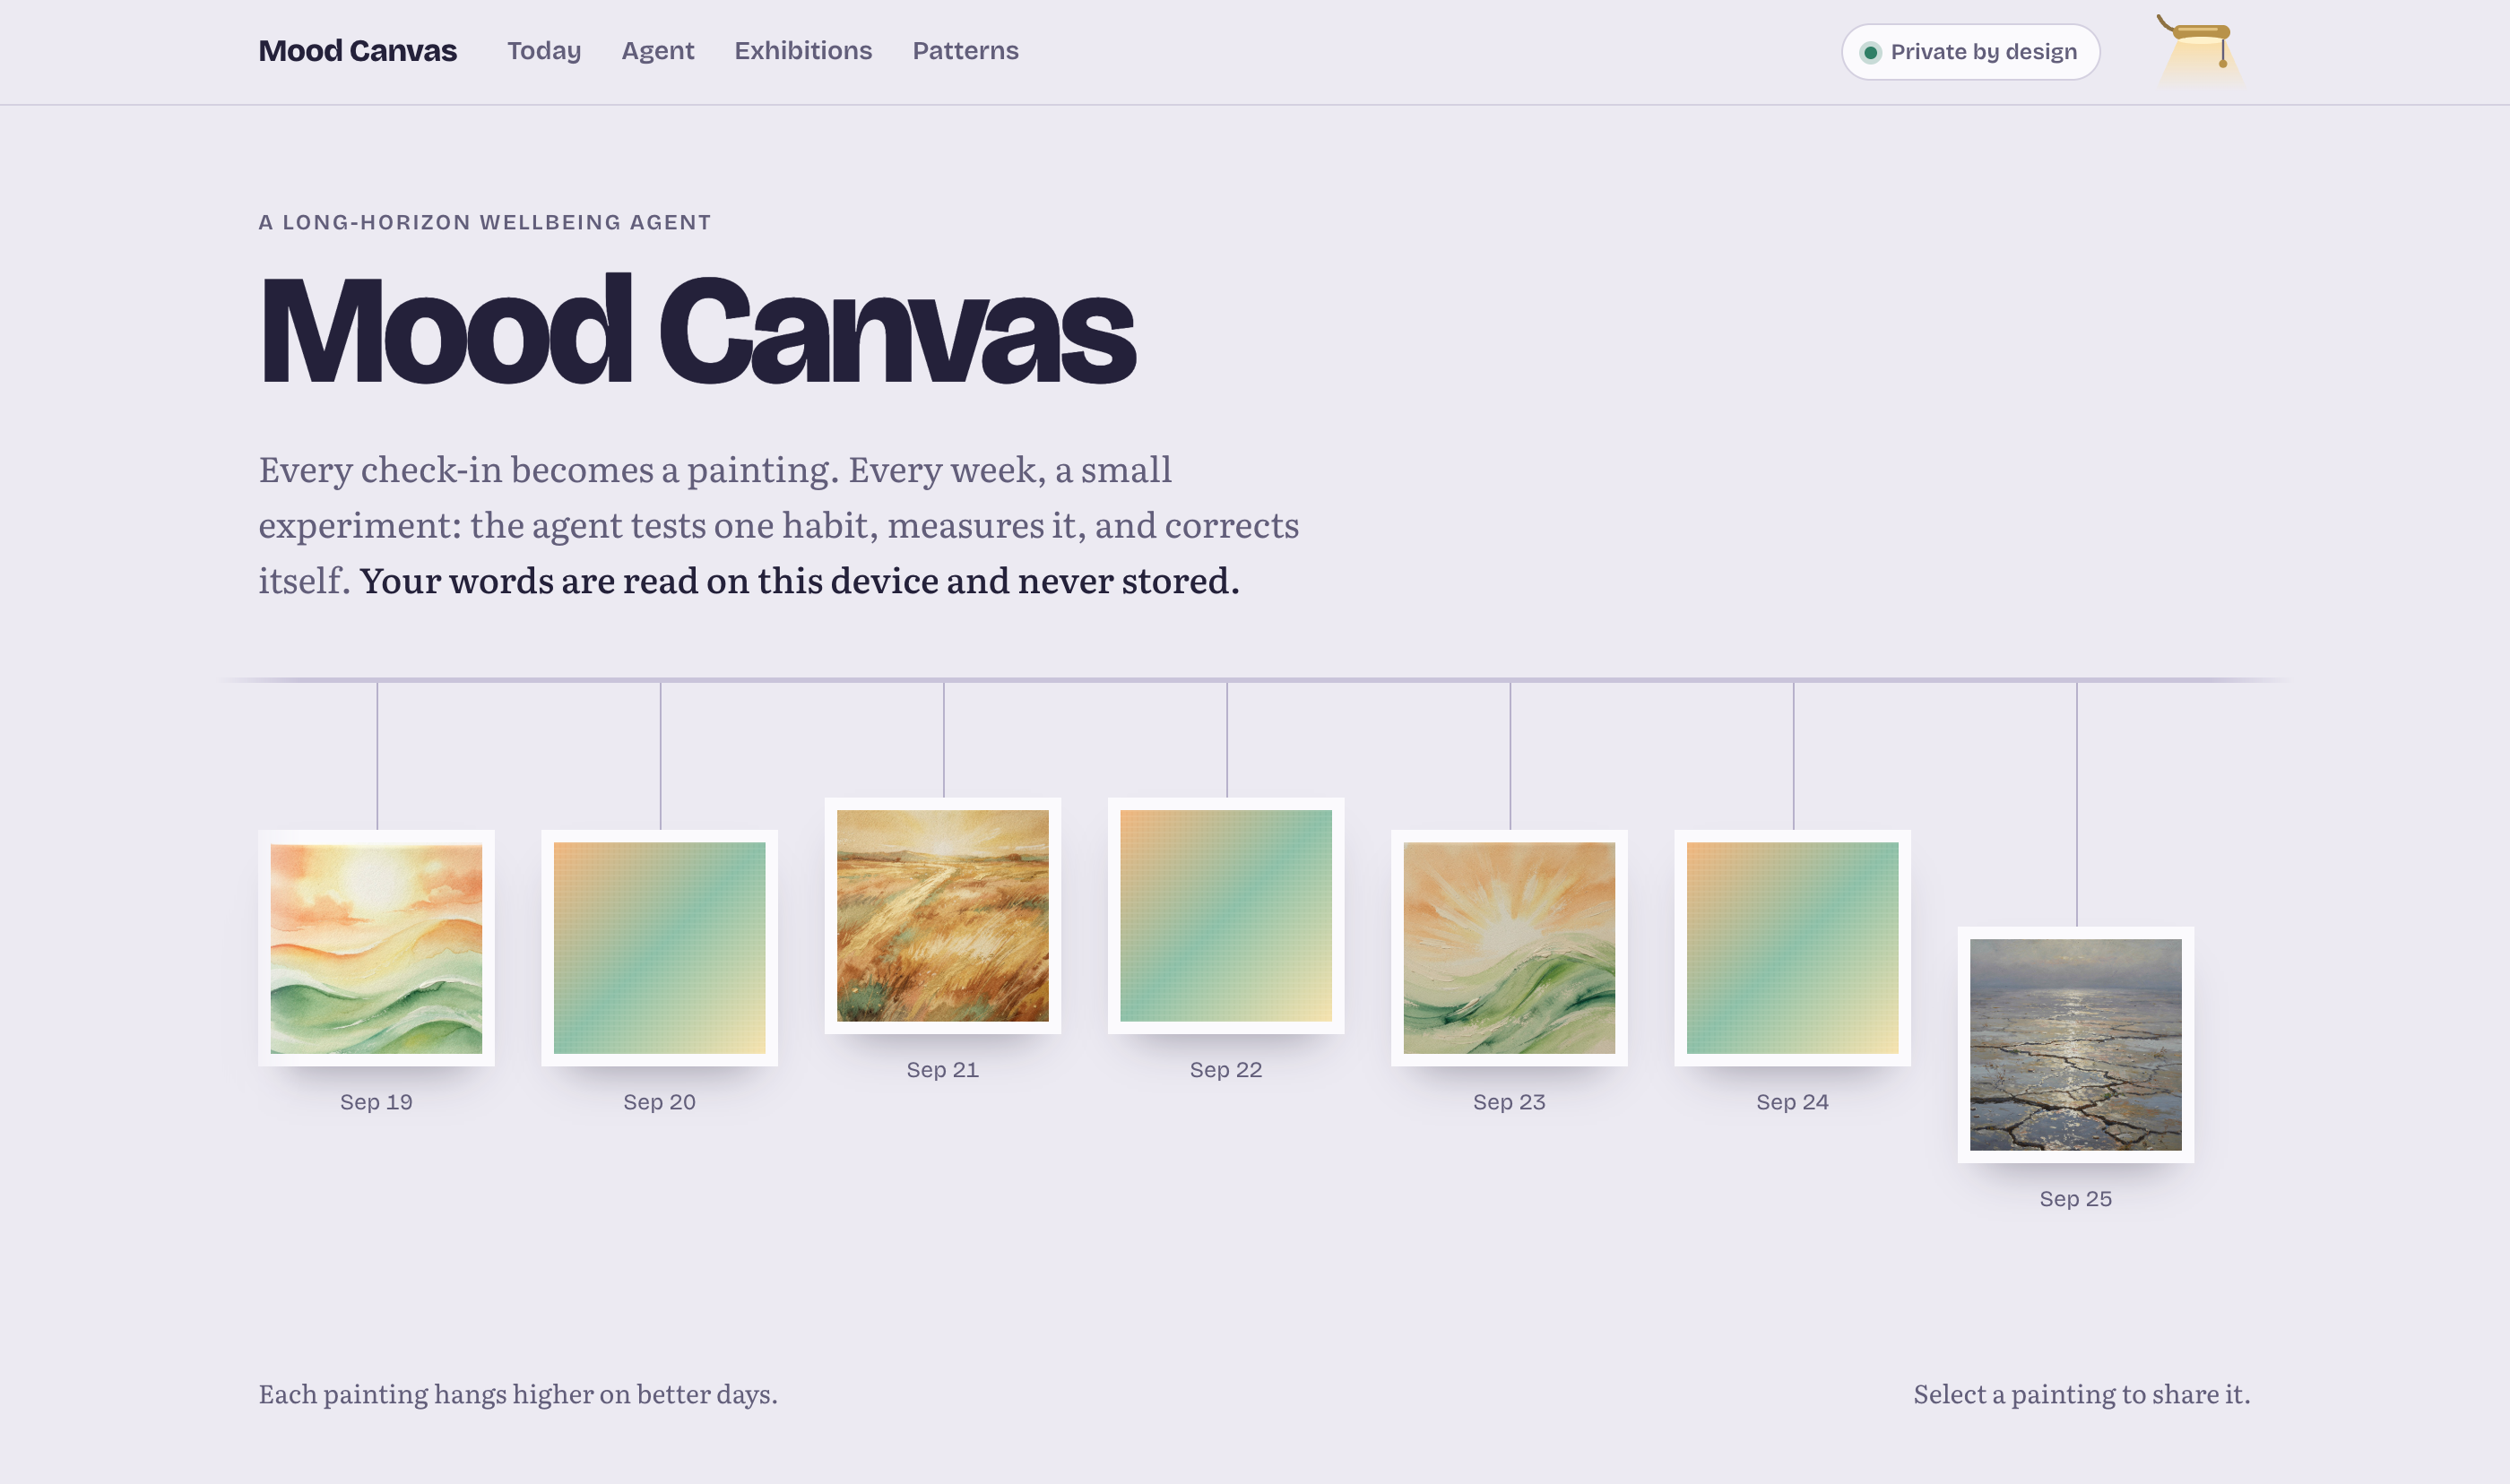
Journaling helps, but nobody rereads their journal. Mood Canvas does it for you, over weeks, as a long-horizon agent. Each check-in (typed or spoken) becomes signals and an abstract painting. Once a week the agent runs one cycle: observe (compare the experiment week with a baseline), correct (a reproducible rule marks the idea supported, rejected, too hard, or needing more data), plan (rank untested causes like sleep, work stress, movement and social contact), and act (start a 7-day habit with one daily question). In our demo it rejects work stress when mood doesn't move, then confirms sleep at +1.4 mood. It never re-reads its history. Its only context is a memory card of about 360 tokens after six weeks. Journal text is discarded after extraction, so the privacy rule and the memory design are the same thing. Liquid AI: LFM2-2.6B runs locally and is the only model that sees your words, with schema-constrained JSON (0 failures in 18 tests). LFM2.5-Audio transcribes voice on-device. LFM2 also breaks near-ties in the agent's plan. Tinybird: stores signals only; the agent reasons from the window_stats and driver_scan endpoints and logs every step. Nimble: finds sources from 9 trusted health sites for each experiment, from a single topic word. Black Forest Labs: flux-2-pro paints each day from an abstract scene and merges each week's paintings into one shareable panorama. Crisis language shows 988 resources, skips the painting, and pauses experiments.
Listed tools (5)
Scroll for moreLiquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.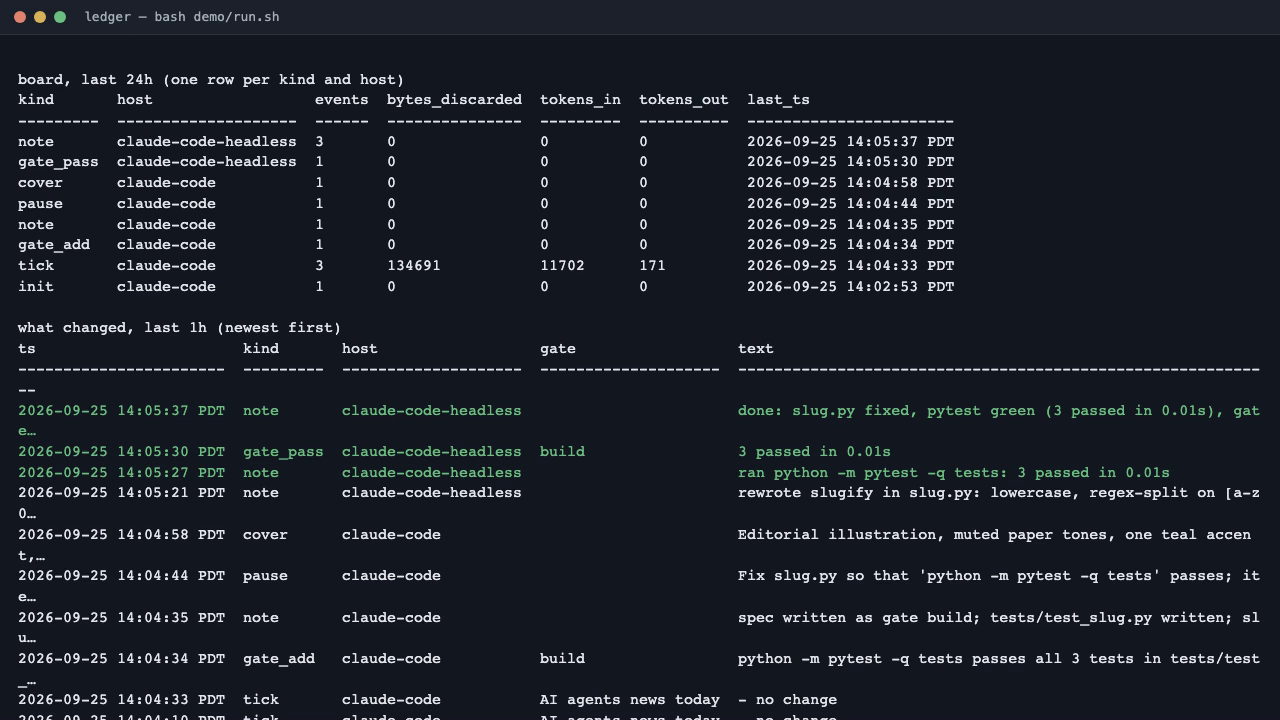
ledger is a host-agnostic command-line tool that keeps a long-horizon agent's state as dated, falsifiable Markdown under `.ledger/`, so the work survives a crash, a context reset or a change of host. The agent's history is disposable; the ledger is the state. Every heading is stamped from the clock, gates flip only on a measurement, and `ledger resume` prints a short brief that a completely fresh session can finish the task from. In the demo the plan is a gate with a threshold and the tests are its measurement: a task paused under Claude Code with failing tests is finished by a new headless Claude Code session whose only context is that brief; it fixes the code, runs the tests, iterates until green and flips the gate with the exact line it measured. Plan, act, observe, self-correct, across a build cycle, without the history. A `watch` loop fetches a page through Nimble, a Liquid LFM2.5-1.2B model running locally through Ollama distills it into at most three new lines, and the raw page is discarded. Every verb emits one event to RawTree, where two SQL queries, what changed in the last hour and the board, answer "what happened" as a query. On pause, Black Forest Labs FLUX renders a cover image from the day's entries. Built with Python 3.11 (standard library only in the core), Claude Code, RawTree, Nimble, Liquid AI and Black Forest Labs.
Listed tools (4)
Scroll for moreLiquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.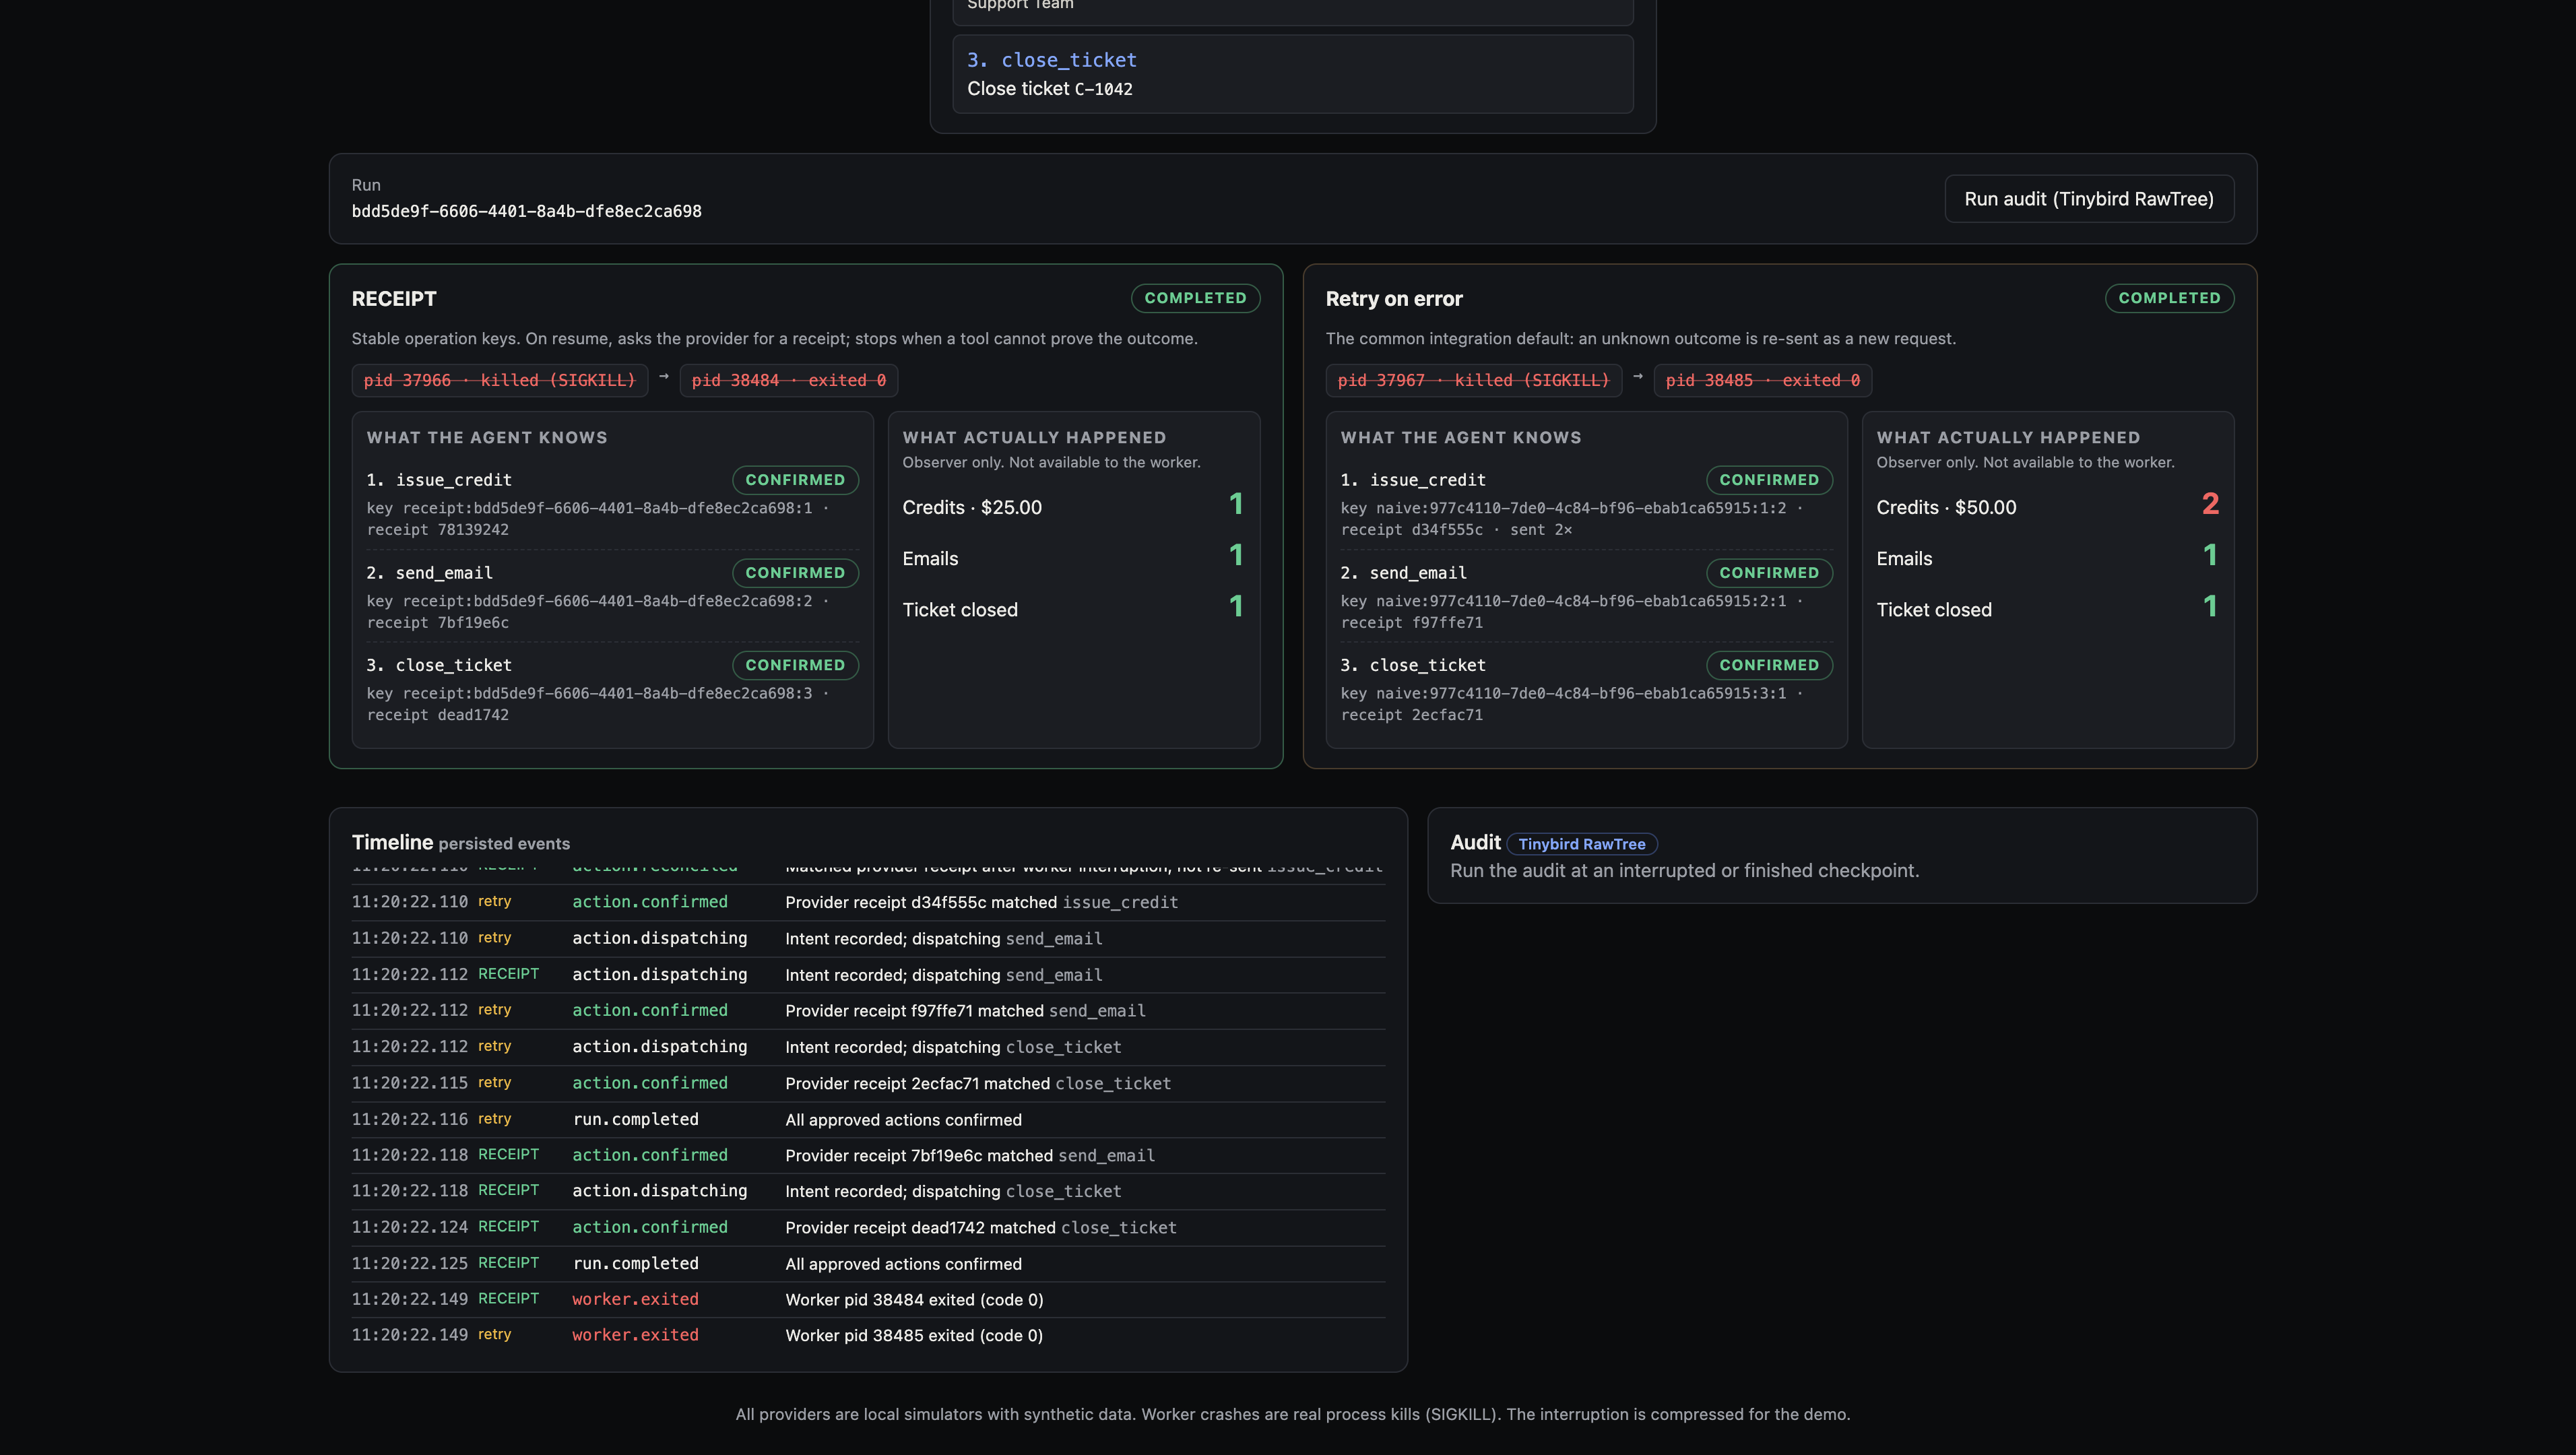
When a support agent crashes mid-refund, it asks for a receipt instead of guessing, so the customer is never (e.g.) credited twice. Support agents now issue credits, send emails and close tickets. The dangerous moment in a long task: the tool acted, but the agent crashed before hearing back. Memory can't help, because the answer never arrived. A naive retry double-credits the customer. How it works: every approved action gets a stable operation key, saved before the call. We SIGKILL the worker right after the credit commits. A fresh process resumes from disk, asks the provider for the receipt under that key, and continues only if the tool, key and payload hash match. Each tool is graded Receipt, Idempotent or Blind; with a Blind email tool, RECEIPT stops and writes a handoff note for a human. Side by side, retry-on-error ends at $50 and two emails; RECEIPT ends at one credit, one email, ticket closed. 18 tests, including real process kills. Tech: Liquid AI LFM2.5 (via OpenRouter) turns the ticket, policy and evidence into a schema-constrained JSON plan, validated in code and approved by a human. Nimble Extract fetches GitHub's real Sept 13 incident page, so the credit rests on evidence. Tinybird RawTree stores every event; the audit query asks "did anything happen twice?" None of them sit on the safety path. Built from my support and customer success work: before an agent touches a customer's stack, ask which tools are agent-safe.
Listed tools (3)
Liquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.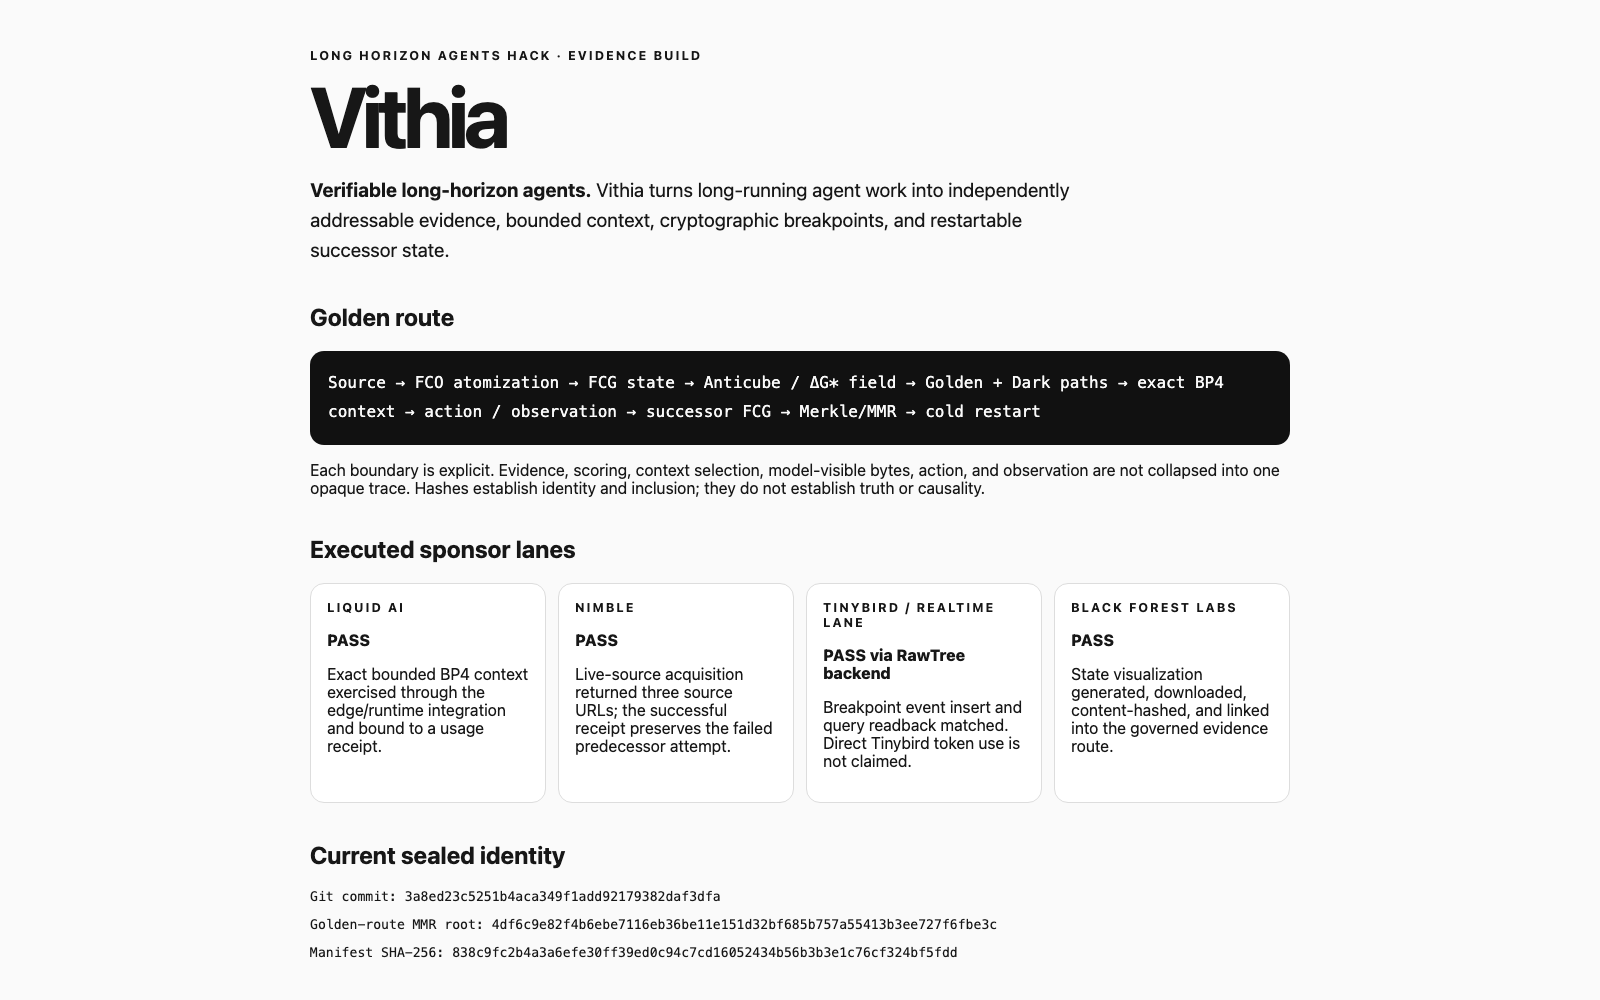
Vithia is a verifiable runtime for long-horizon agents. Instead of treating a long conversation or task history as one opaque context window, Vithia turns work into independently addressable evidence objects (FCOs) connected in a temporal evidence graph (FCG). Each cycle records the source event, atomization, policy/field state, candidate Golden and Dark paths, the exact bounded context shown to the model, and the successor state. Canonical object hashes are appended to Merkle/MMR breakpoints so a later agent can reconstruct what existed and what the model actually saw without claiming that a hash proves the truth of the content. The demo executes a real cold restart: the agent process is killed, then reconstructs the same bounded context and custody state from the persisted object store rather than the original conversation. We also integrated sponsor lanes: Liquid AI for bounded-context inference, Nimble for external web evidence, RawTree/Tinybird for persistent telemetry, and Black Forest Labs for generated visual evidence. LongMemEval-V2 provides the benchmark lane. The goal is durable, inspectable agent state that can grow in total evidence while keeping active context bounded.
Listed tools (5)
Scroll for more OpenAIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Liquid AIpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.TinybirdpendingAdded by the builder while publishing buildstuff. Pending catalog review before becoming a public tool profile.Black Forest LabspendingAdded by the builder while publishing trexpush. Pending catalog review before becoming a public tool profile.NimblependingAdded by the builder while publishing Dinopush. Pending catalog review before becoming a public tool profile.

Greplica runs a portable reviewer-and-coder loop for GitHub pull requests. A reviewer agent scores the change, reports blocking findings, and hands them to a coding agent. The coding agent repairs the branch and pushes updates, then the reviewer checks the new version until it reaches the approval threshold or the repair limit. Band coordinates the persistent reviewer and coding agents and creates a dedicated room for each pull request. Senso supplies repository context retrieved from ingested pull-request markdowns. The team benchmarked four context strategies on Autoloops/greplica PR #176—including no context, a gold context file, live GitHub context, and Senso-native context—and documented how context changes repair quality and speed.
Listed tools (2)
 BandEnterprise-grade communication infrastructure for AI agents.

Lattice is a local-first workspace designed for people who think across documents, structured data, code, and AI. Instead of separating notes, databases, whiteboards, files, and automations into different applications, Lattice brings them together in a single open platform built around standard file formats and a fast native desktop experience. Your data remains yours, stored locally and organized in a way that’s human-readable, portable, and accessible to both people and AI. Beyond note-taking, Lattice serves as a foundation for intelligent workflows. Built-in AI can understand and organize your workspace, search across structured and unstructured data, generate content, automate repetitive tasks, and connect to external tools through an extensible plugin and MCP ecosystem. Optional cloud services add encrypted backup, sharing, publishing, and scheduled automations without sacrificing the local-first architecture, giving you the speed and privacy of a desktop application with the convenience of modern cloud collaboration. We use Pioneer to provide an affordable integrated AI agent which can do embedded and hybrid search over the workspace's embeddings via a local Actian AI DB instance.
Listed tools (2)
 PioneerModel routing, adaptive inference, and agentic fine-tuning platform.
 ActianPortable vector database for edge AI

Sift is a cognitive governance layer that sits in front of AI assistants to reduce cognitive offloading. Instead of immediately answering every prompt, Sift evaluates whether the user has demonstrated independent thinking or is relying entirely on AI to reason for them. When excessive cognitive offloading is detected, the system temporarily intervenes with Socratic questions that encourage users to form their own hypotheses before receiving AI assistance. By promoting active reasoning rather than passive consumption, Sift aims to preserve critical thinking while maintaining AI as a collaborative tool rather than a replacement for human cognition.
Listed tools (1)
Matches clinical trials to patients based on EHR data and sends emails to them. Uses pioneer and guild.
Listed tools (2)
 Guild.aiThe control plane for AI agentsPioneerModel routing, adaptive inference, and agentic fine-tuning platform.

CONFESSION is an external referee for AI coding agents. When a builder agent announces that a task is finished, its self-report is ignored. An independent Auditor agent hands the claim to Replay.io's autonomous QA API, which explores the actually deployed app and returns a root-cause verdict with a shareable report URL. That verdict drives real consequences with no human in the loop. A FALSE_CLAIM immediately revokes the agent's write tools via a Guild.ai tool-grant demotion, and the caught lie is added to a Pioneer training set so a LoRA fine-tune yields a more honest successor. A VERIFIED result advances a ratchet; enough consecutive passes promote the agent to a more powerful tier, and any lie knocks it back down. Nothing is staged: a real CRUD target app, no planted bugs, live API verdicts, real workspace state transitions, and a real fine-tune job. A receipts view dumps live state (Replay report links, Guild session JSON, Pioneer job IDs) so judges can verify instead of trusting the demo. The result is autonomy an agent has to earn against ground truth, continuously and with receipts.
Listed tools (3)
Guild.aiThe control plane for AI agentsPioneerModel routing, adaptive inference, and agentic fine-tuning platform. Replay.ioDrop-in QA for web apps

Plato Autopilot — A Governed Team of AI Restaurant OperatorsPlato Autopilot is a multi-agent restaurant management system that turns live operational data into measurable business improvements. A General Manager agent coordinates specialized agents for inventory, menu optimization, revenue, kitchen operations, and purchasing. Each agent has its own expertise, data access, and tools, with identities, permissions, and activity governed through Guild AI. Together, the agents identify high-impact opportunities, propose measurable goals, and safely execute approved actions—such as promoting specific menu items, allocating expiring inventory, adjusting kitchen preparation, or drafting supplier-order changes. Plato then measures the results against independent demand, updates restaurant records in real time, and learns from both successful and failed experiments. It is an auditable, continuously improving team of AI operators that closes the loop: **Observe → collaborate → govern → execute → measure → learn.**
Listed tools (3)
Guild.aiThe control plane for AI agentsPioneerModel routing, adaptive inference, and agentic fine-tuning platform.Replay.ioDrop-in QA for web apps
Kindred is a semantic matching platform that builds a live graph of the people closest to you in meaning, and shows the reasoning behind every match instead of just a score. Drop in your context, and the Profiler builds a semantic vector of how you think. The Matcher scores and ranks candidates against it, and the graph reorganizes live as the model updates. Click any node and the Introducer explains the actual reasoning behind the match. The Evaluator tracks which connections land and feeds that signal back, so closeness is a learned function, not a fixed similarity score. On /village, the same matching process plays out as a pixel-art town where agent-villagers deliberate a match out loud and reach consensus, built to be data-driven and livestream-ready. Built with Actian for vector storage, Fastino for fine-tuning the Matcher on real landing data, Gemini for profiling and reasoning generation, BAND for intro threads, and Guild for weight versioning. Four agents, one shared contract, five hours of ideation before a single line of implementation.
Listed tools (12)
Scroll for moreActianPortable vector database for edge AIBandEnterprise-grade communication infrastructure for AI agents.PioneerModel routing, adaptive inference, and agentic fine-tuning platform.Guild.aiThe control plane for AI agentsA patient calls the clinic. Donna (VAPI + Twilio + Deepgram, Gemini in-call) answers, transcribes live onto the receptionist console, extracts structured symptoms/meds/allergies, and matches or creates the patient record — with a one-click identity-repair flow when ASR mis-hears a name. A deterministic, clinician-tunable triage engine (35 unit tests, no LLM in the acuity decision) scores every call ESI 1–5; life-threat patterns like chest pain + left-arm radiation hard-gate to Level 1 and Donna verbally instructs the caller to dial 911. The doctor opens a pre-built chart, a SOAP note streams in with ICD-10 codes and red-flag pre-scan, edits, and signs. Self-evolution is measured, not claimed: Donna's pristine AI draft is saved before any human edit, and the word-level edit distance per successive call is charted live — plus doctor corrections POST back to Pioneer's adaptive inference as labeled examples, and signed revisions distill into embedded clinical lessons retrieved into the next similar encounter (vector search on-prem via Actian VectorAI/MiniLM, so PHI never leaves the clinic). Every agent and human action is audited with tamper-evident hashes. Live phone number, real calls, offline-safe canned demo. 72 passing tests.
Listed tools (3)
Replay.ioDrop-in QA for web appsPioneerModel routing, adaptive inference, and agentic fine-tuning platform.ActianPortable vector database for edge AI
Listed tools (2)
PioneerModel routing, adaptive inference, and agentic fine-tuning platform.Replay.ioDrop-in QA for web appsPrompt injection is why enterprises won't give agents write-access, and every defense today is static. Immune closes the loop: two LLM agents co-evolve — an attacker probing whatever isn't yet covered, and a defender that patches itself when breached. The defender is guarded at the action boundary, just before a sensitive tool call fires. On a breach, synthesis reads the agent's own raw trace and emits an antibody: a rule in a composable predicate language. The LLM composes freely; nothing it writes runs as code — we interpret a closed grammar. Every candidate faces a three-sided gate: replay the attack (must block); replay 8 mutations — recipient zero-width-split, amount regrouped as $4,850.00, pretext reworded — all of which must block, rejecting rules that only memorized one payload; and 12 benign tasks, 2 needing a real payment, so a patch can't buy security by lobotomizing the agent. We plot co-evolution, not attack success rate: a breach means the attacker found uncovered ground — its job. Sword = verified defenses in force when it still got through (0→4). Shield = attack variants provably blocked (9→38). Senso: versioned antibody library — gen 4 defeated a live rule, promoting a native v2. Band: attacker, defender and peer as registered agents; promotion broadcasts a quarantine advisory the peer drains. Actian: OpenAI-embedded signatures scoring attack novelty. Claude drives all three agents. Replay QA'd the console.
Listed tools (4)
Scroll for moreActianPortable vector database for edge AIBandEnterprise-grade communication infrastructure for AI agents.Replay.ioDrop-in QA for web apps
Dark Harvest is a mission-operations prototype that continuously monitors NASA/JPL Deep Space Network links, OpenSky aircraft, and CelesTrak satellite data.
Listed tools (3)
BandEnterprise-grade communication infrastructure for AI agents.PioneerModel routing, adaptive inference, and agentic fine-tuning platform.Small businesses in Latin America (Specially the Dominican Republic and Colombia) sell on WhatsApp, in voice notes and slang. DeUna answers as the owner — same voice, same selling style, same price floor. When it meets something it was never taught — a cracked-screen trade-in, a discount below the floor — it doesn't invent a number. It asks the owner on WhatsApp, with its own recommendation and Aprobar / Rechazar / Otro monto buttons. One tap. The ruling is saved to Senso as policy, and the next customer asking the same thing gets an instant quote, no escalation. It gets smarter every time the owner teaches it. Customers send voice notes, so it replies with one — transcribed by ElevenLabs Scribe v2, spoken back in the owner's cloned voice with room tone so it sounds recorded behind the counter. Guild.ai is the agent runtime: policy search, owner escalation, catalog, checkout. Senso.ai is the memory that makes the loop self-evolving. Pioneer routes each turn — DeepSeek-V4-Flash for easy questions, Claude Sonnet for hard trade-ins. ElevenLabs does voice both ways. It negotiates inside a confidential floor price and closes with a payment link.
Listed tools (3)
Guild.aiThe control plane for AI agentsPioneerModel routing, adaptive inference, and agentic fine-tuning platform.
The QA agent that gets **cheaper** **every time you ship**. Replay QA finds real bugs in a live app, Ratchet fixes them, and a fix enters memory only once a re-test confirms it worked. Next time that cause appears, anywhere, it costs one AI call instead of four. Verified fixes publish, so they cross teams.
Listed tools (4)
Scroll for moreActianPortable vector database for edge AIPioneerModel routing, adaptive inference, and agentic fine-tuning platform.Replay.ioDrop-in QA for web appsEvolving Poker is a live agent-evaluation playground where three AI models compete in a simplified poker game and adapt their strategies after every hand. Each player starts with the same strategy—aggression, bluff rate, and call threshold—while a deterministic game engine handles cards, betting, and legal actions. After each hand, the agents review the outcome and decide whether to change their strategy or keep it unchanged. Every update is shown as a readable diff, allowing viewers to compare which model learns effectively, which overreacts to noisy results, and which offers the best balance of performance, latency, and cost. Pioneer runs and compares the models, Band coordinates the agents and records their reflections, and Replay tests the spectator dashboard. The final tournament results and evolution history are published to cited.md, with the full audit report available through an x402-protected endpoint.
Listed tools (3)
BandEnterprise-grade communication infrastructure for AI agents.PioneerModel routing, adaptive inference, and agentic fine-tuning platform.Replay.ioDrop-in QA for web appsI have an LLM Judge that tracks coding agent turns and user input and judges the coding agent output and if it's satisfactory for the user. The goal is to reduce LLM coding friction and increase coding agent understanding of user intention. The platform also supports trace-tracking for when errors occur, or when critical infrastructure problems arise. The traces are logged, and using deterministic checks, it would not occur again. So, in total, it tracks errors, mistakes, coding agent turns, user turns, and improves the LLM judge over time through these traces. Users are also able to fine-tune their own model through these traces and specifically create a model just for themselves.
Listed tools (4)
Scroll for moreActianPortable vector database for edge AIPioneerModel routing, adaptive inference, and agentic fine-tuning platform.Replay.ioDrop-in QA for web appsEvent Copilot is a self-improving event-recommendation agent. It helps a user choose events for networking, knowledge, and opportunity outcomes; creates a measurable attendance mission; publishes grounded output; and learns from post-event feedback so later rankings improve.
Listed tools (3)
ActianPortable vector database for edge AIBandEnterprise-grade communication infrastructure for AI agents.Build a search experience that understands intent, supports filters, and can move from local prototype to hosted vector search.
Suggested tools
Route a task through planning, tool calls, validation, and human review without losing observability.